Training Robust Neural Networks
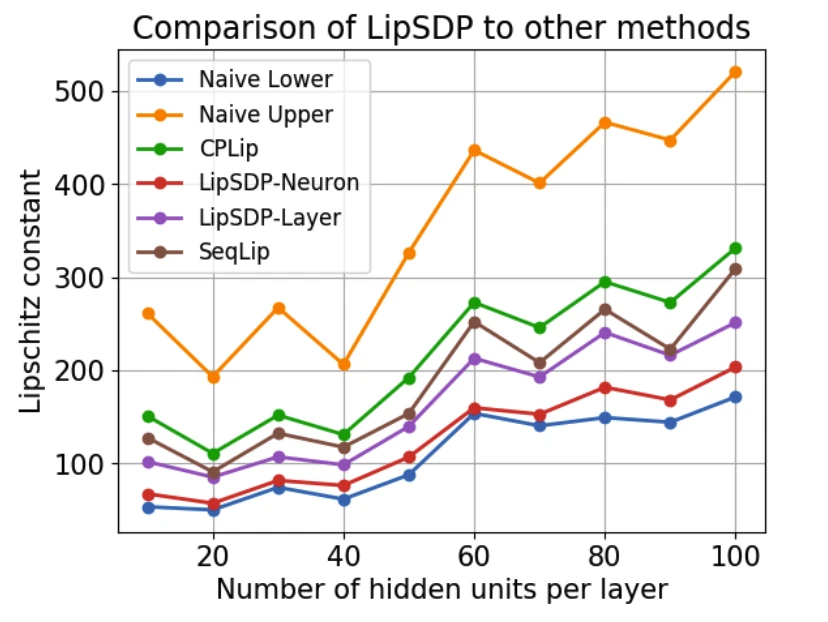
Implemented Lipschitz-constant based regularization for training robust neural networks and compared performance against L2 and other baseline techniques.
Implemented Lipschitz-constant based regularization for training robust neural networks and compared performance against L2 and other baseline techniques.