Convexifying Neural Networks
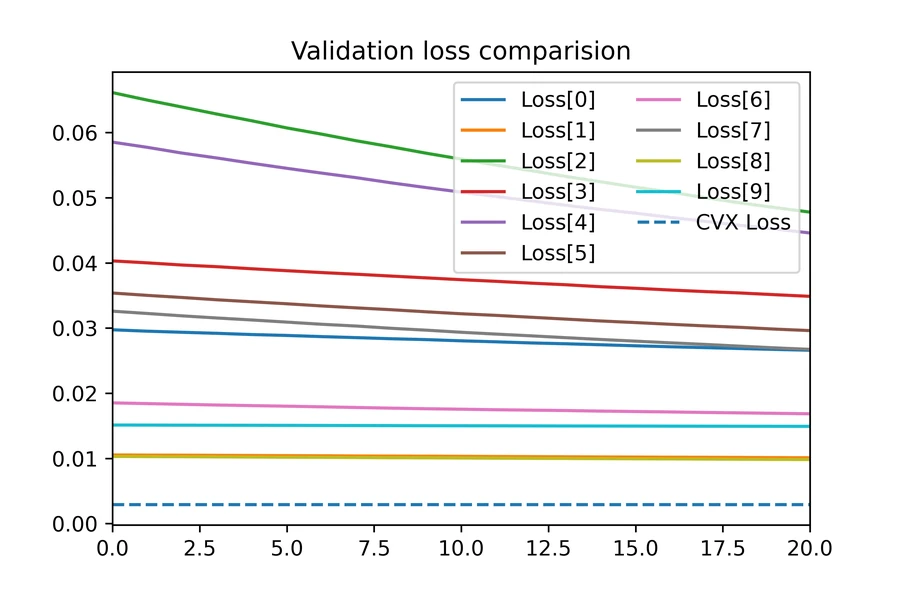
Implemented the exact convex reformulation of two-layer ReLU network training, whose solution yields a globally optimal network, and compared it against networks trained with SGD.
Implemented the exact convex reformulation of two-layer ReLU network training, whose solution yields a globally optimal network, and compared it against networks trained with SGD.